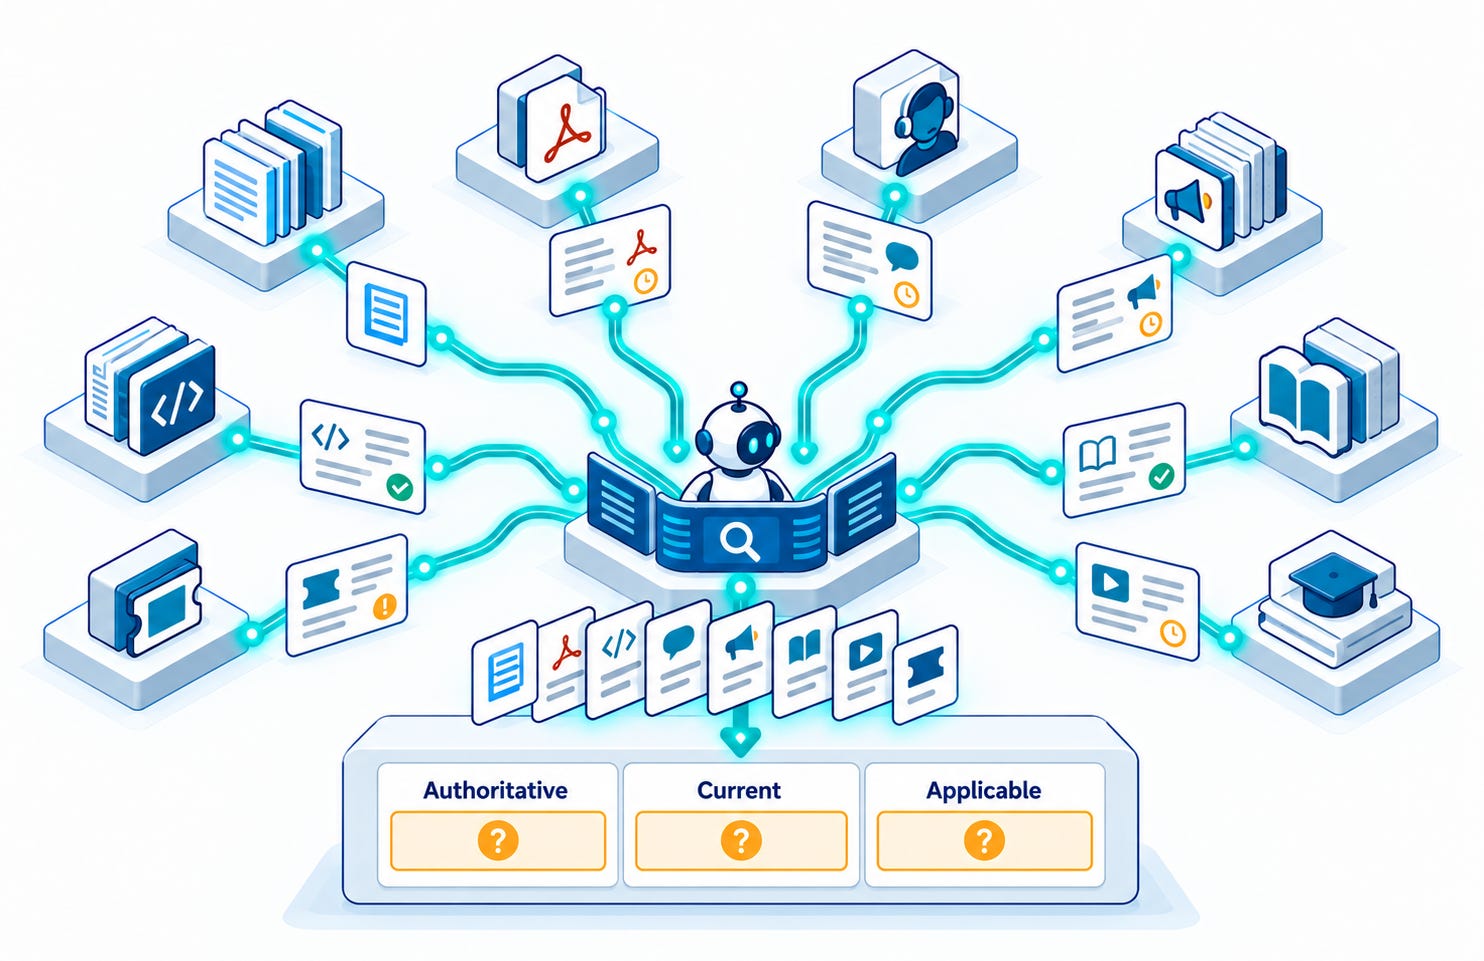
I’m a regular reader of MIT Technology Review Insights. While researching AI and content-production scalability for an upcoming conference panel discussion, I found its August 2026 report, Scaling AI agents with trustworthy data.
The subject? Enterprise data systems. The problems it identified sounded familiar:
info scattered across systems
unstructured content that’s difficult for AI to use
missing context and semantics, and
unclear relationships between info and the situations to which it applies
The Access Problem
In early 2026, MIT Technology Review Insights surveyed 300 senior leaders in data, technology, product, and AI roles. It also interviewed execs to add context to the survey results. Most respondents worked for big organizations with annual revenues of $500 million or more.
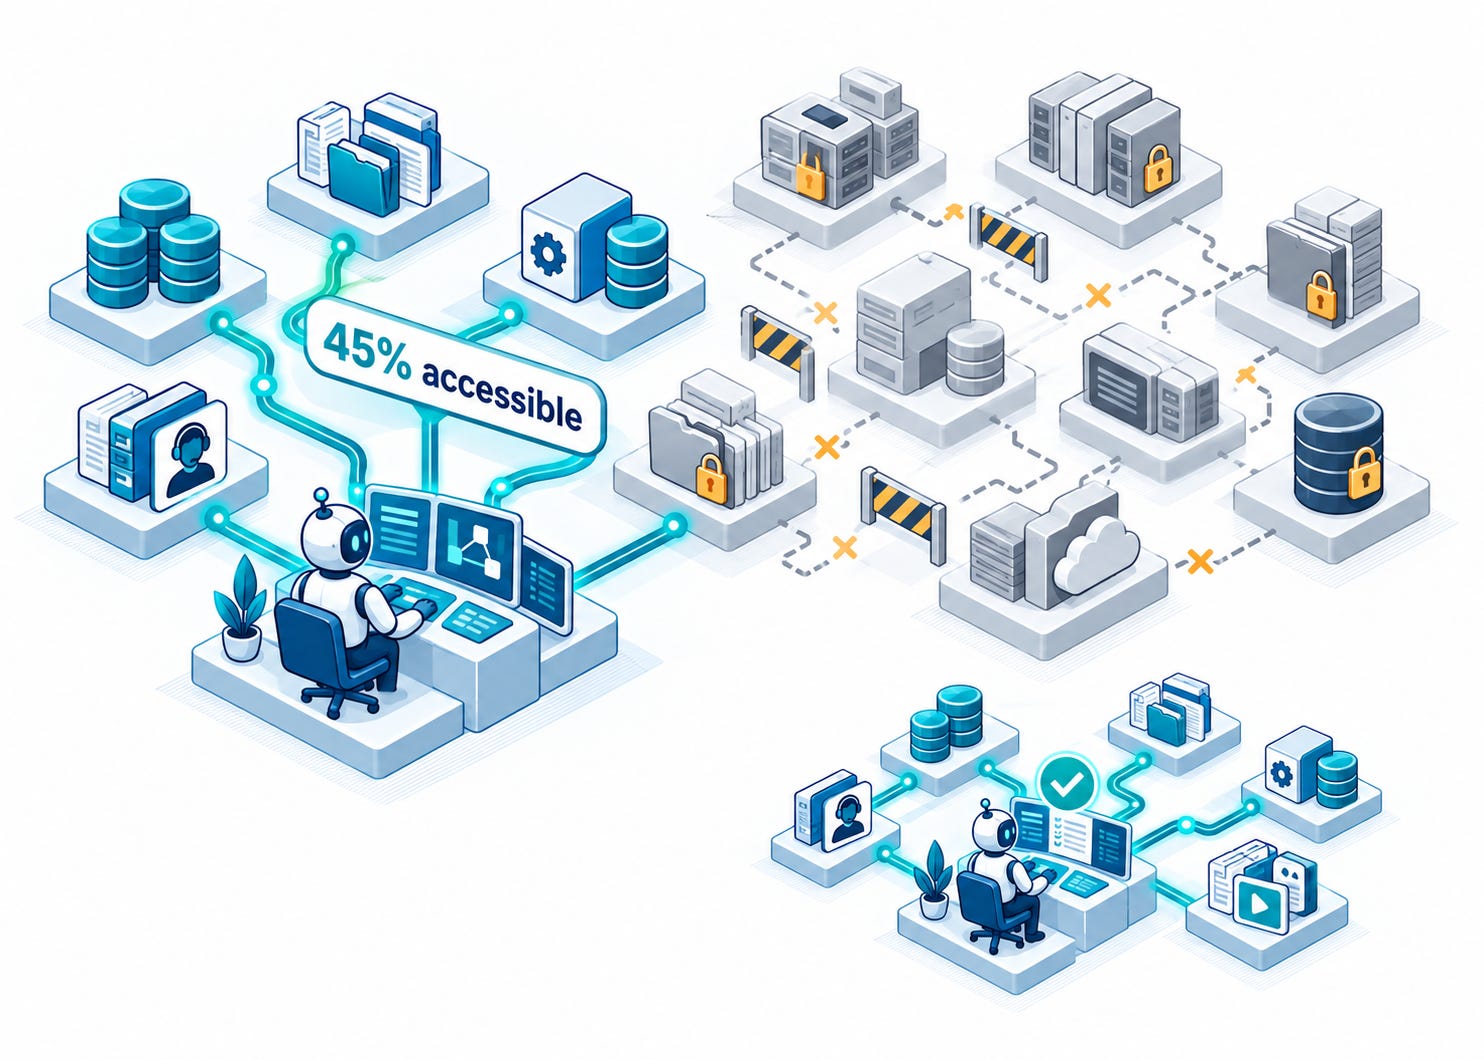
Survey respondents said their AI systems can access, on average, only 45% of their organization’s data. Given how messy corporate content can be, I expected a low number; but 45% feels less like a statistic and more like an indictment.
Researchers call those orgs whose AI can access 30% or less of their data “data laggards.” A smaller group says its AI systems can access more than 70% of enterprise data, and those same orgs also say they’re seeing success with AI agents.